Animate a Photo: Turn a Product Photo into Video
Photo to video With your own photoFull vertical 9:16 1 try
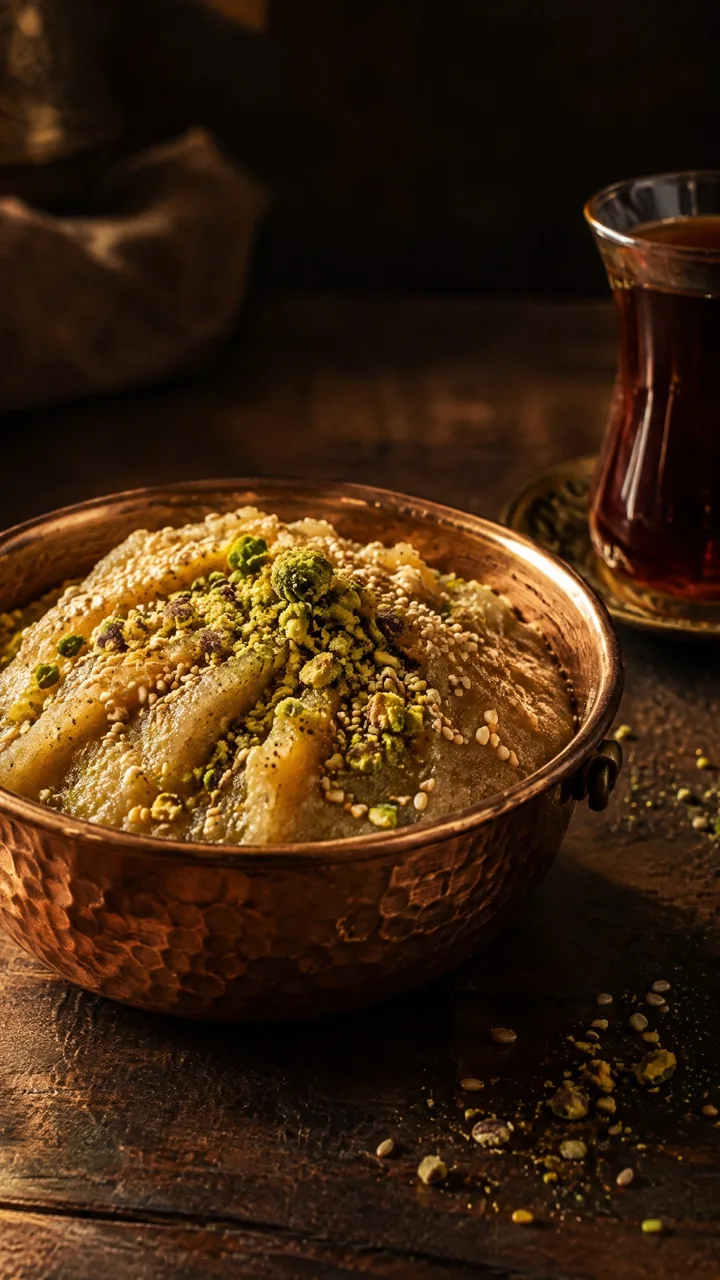
ASMR food video from this photo of our own dish. Camera: [static macro close-up with a very slight, slow push-in]. Action: [a brass spoon slowly cuts into the tahini semolina halva], [lifts a portion, and a few crumbs and pistachio pieces fall back into the copper bowl]. The dish stays exactly as in the photo: same food, same bowl, same garnish; do not add ingredients. Sound: only close-up sounds - [the soft crumble of the halva and the spoon gently touching the copper bowl]; no music, no voice. Warm candlelight, natural speed.Replace the gold [bracketed] parts to match your own product, space or brand.
The prompt tells the model not to change these. Check the result anyway: these are the parts that break most often.
Only use it with a photo of a dish you actually sell: the cross-section, consistency and texture in the video are the model's guess; the real dessert cuts differently. Don't present it as "real footage" on your menu or on a food delivery platform.
If you'll use it in ads, disclose that the video was generated with AI. Misleading food visuals are the AI use that draws the most backlash for restaurants.
Creates a close-up ASMR video, with sound, of a spoon or knife cutting into your own dessert or dish, from a photo of it. This is the most-watched short video format for patisseries, dessert shops and restaurants.
In the square brackets, change the cutting utensil, the action and the sound. Limit the sound with "only close-up sounds, no music or voice"; otherwise the model may add music. Don't add ingredients: don't write in sauce or cream that isn't in the photo.
The example was generated with Kling 3.0 via Higgsfield (5 sec, with sound).
What happened across attempts: On the first attempt, the spoon cut into the halva and lifted a portion, crumbs fell, and the sound of the spoon touching the copper came through. The fingertip holding the spoon enters the frame for a moment. The texture of the halva's cross-section is the model's guess.
Even with the same prompt and the same settings, you won't get an identical result: models generate something different every time. The example shows what kind of result this prompt produces; it is not a guarantee.
We use cookies to improve the site and measure advertising performance. Analytics and advertising cookies run only if you accept them. Details are in our Privacy Policy and Data Protection Notice.